CARLA Sensor Data Lake
Turn the open-source CARLA simulator into a synthetic autonomous-driving data lake on Backblaze B2: define scenarios, capture multi-sensor episodes (camera, LiDAR, depth, segmentation, telemetry), and browse and serve the datasets straight from B2.
Built for: Autonomous-vehicle researchers, perception-model engineers, and robotics/sim teams who need scalable synthetic sensor datasets on cheap object storage.
What it's built with
Each piece of the stack, and the job it does in this project.
- Next.js 16 + React 19
- Web UI
- Tailwind v4, shadcn/ui, Recharts, TanStack Query
- Design system and charts
- FastAPI + Pydantic v2 (Python 3.12+)
- Backend API
- boto3 over the S3-compatible API
- B2 storage access
- CARLA 0.9.x
- Driving simulator (optional, user-hosted)
- PyTorch
- DataLoader training example (optional)
- Backblaze B2
- Object storage — the data lake
Core capabilities
What the project does out of the box, before you write any code of your own.
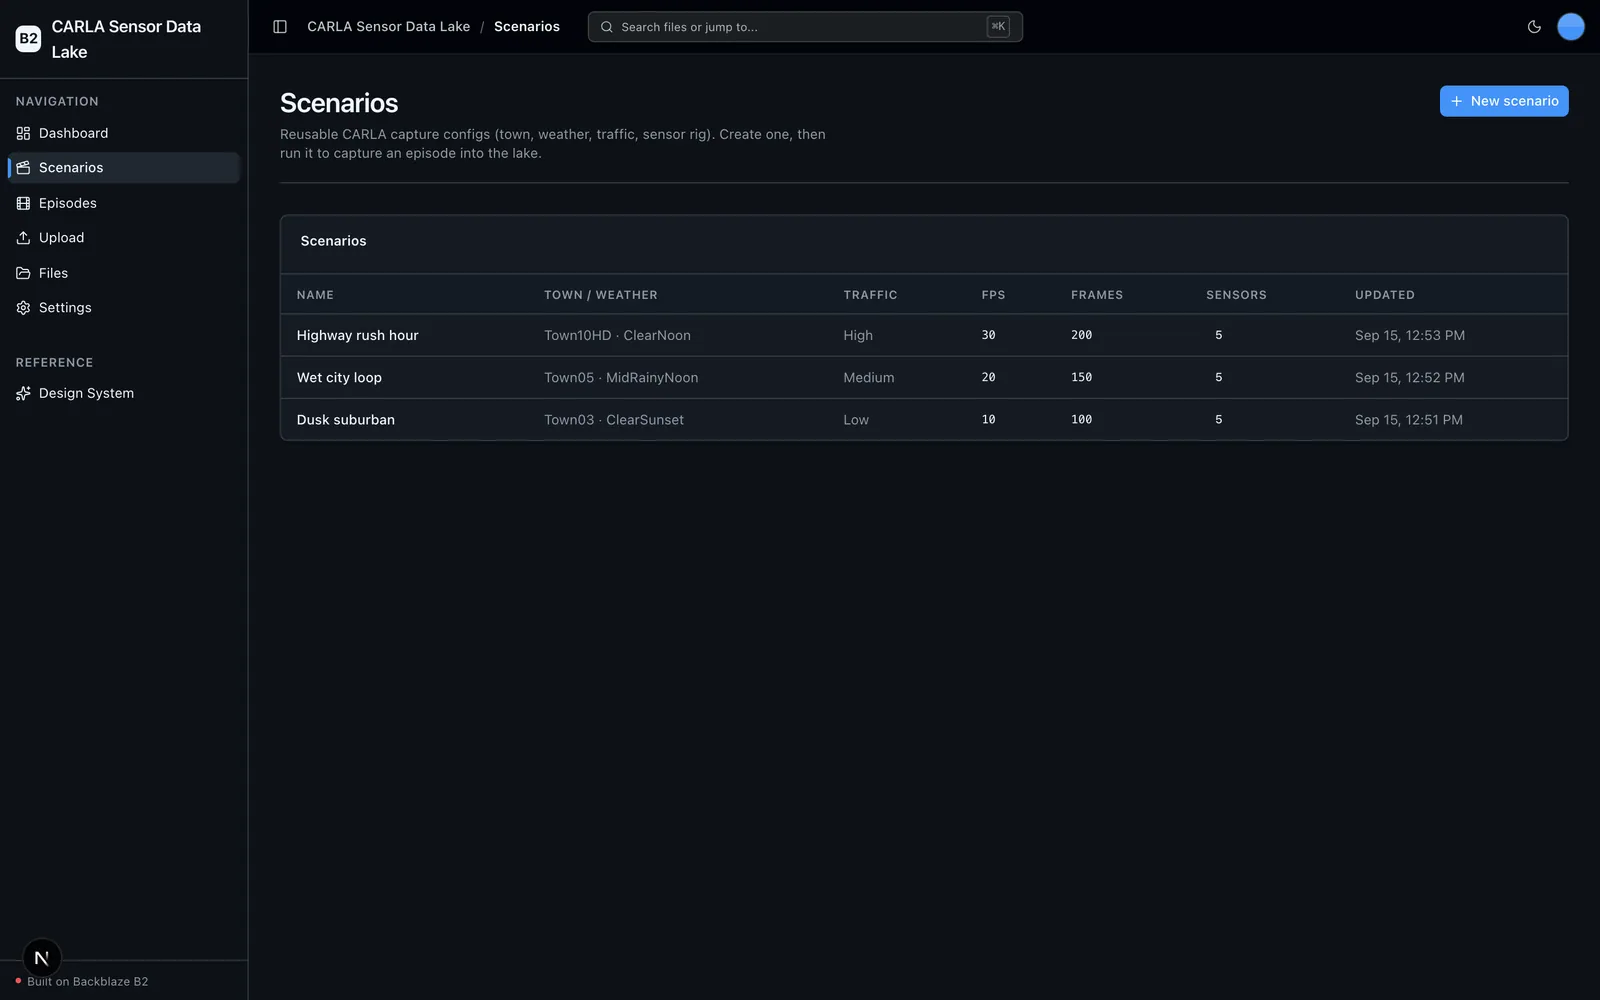
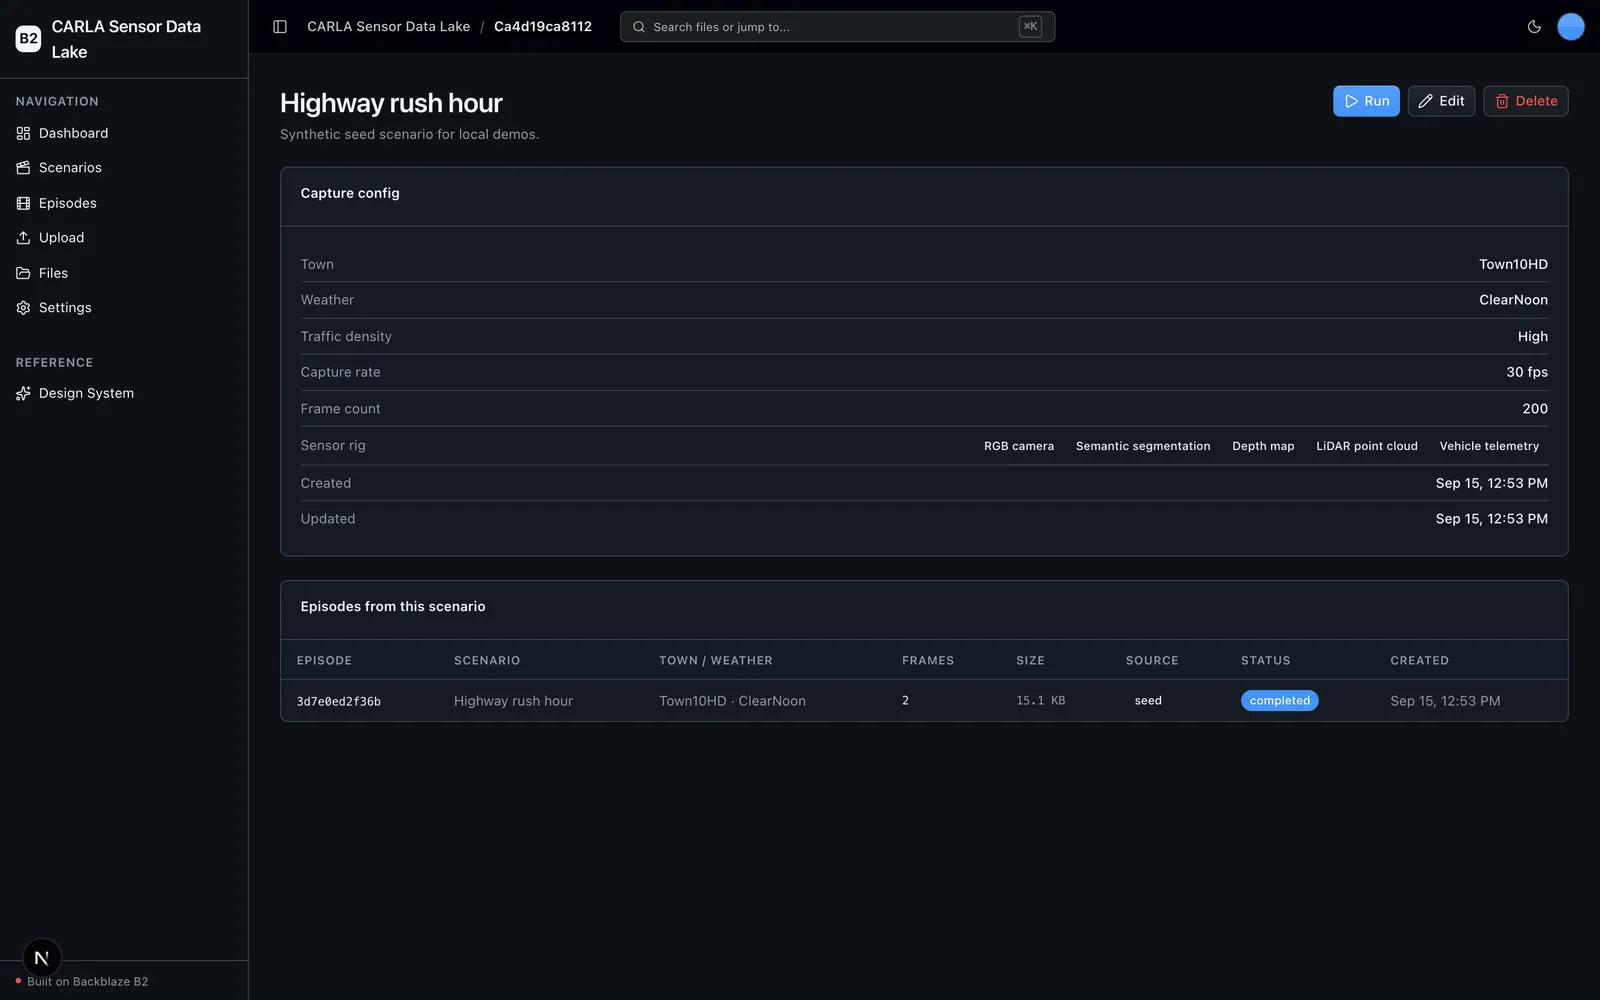
Scenarios
Create, edit, delete, and run reusable CARLA capture configs (town, weather, traffic, sensor rig), stored as JSON in B2.
Simulation runner
Drives the real CARLA server in synchronous mode and streams multi-sensor frames to B2 as they are captured.
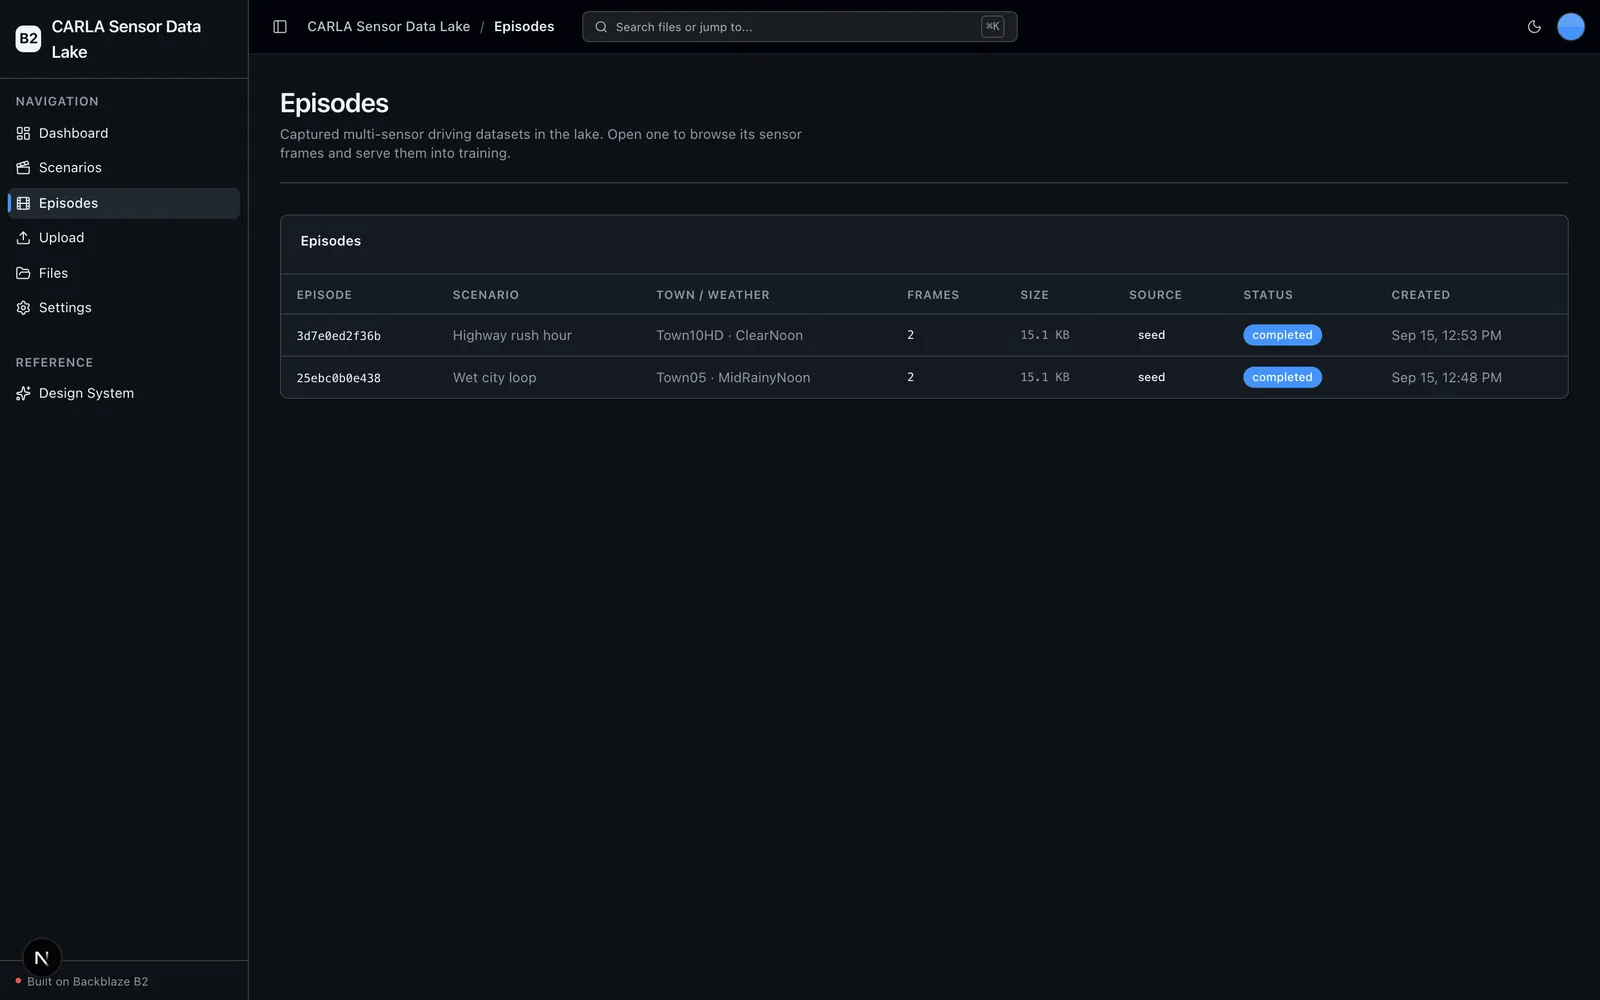
Episode explorer
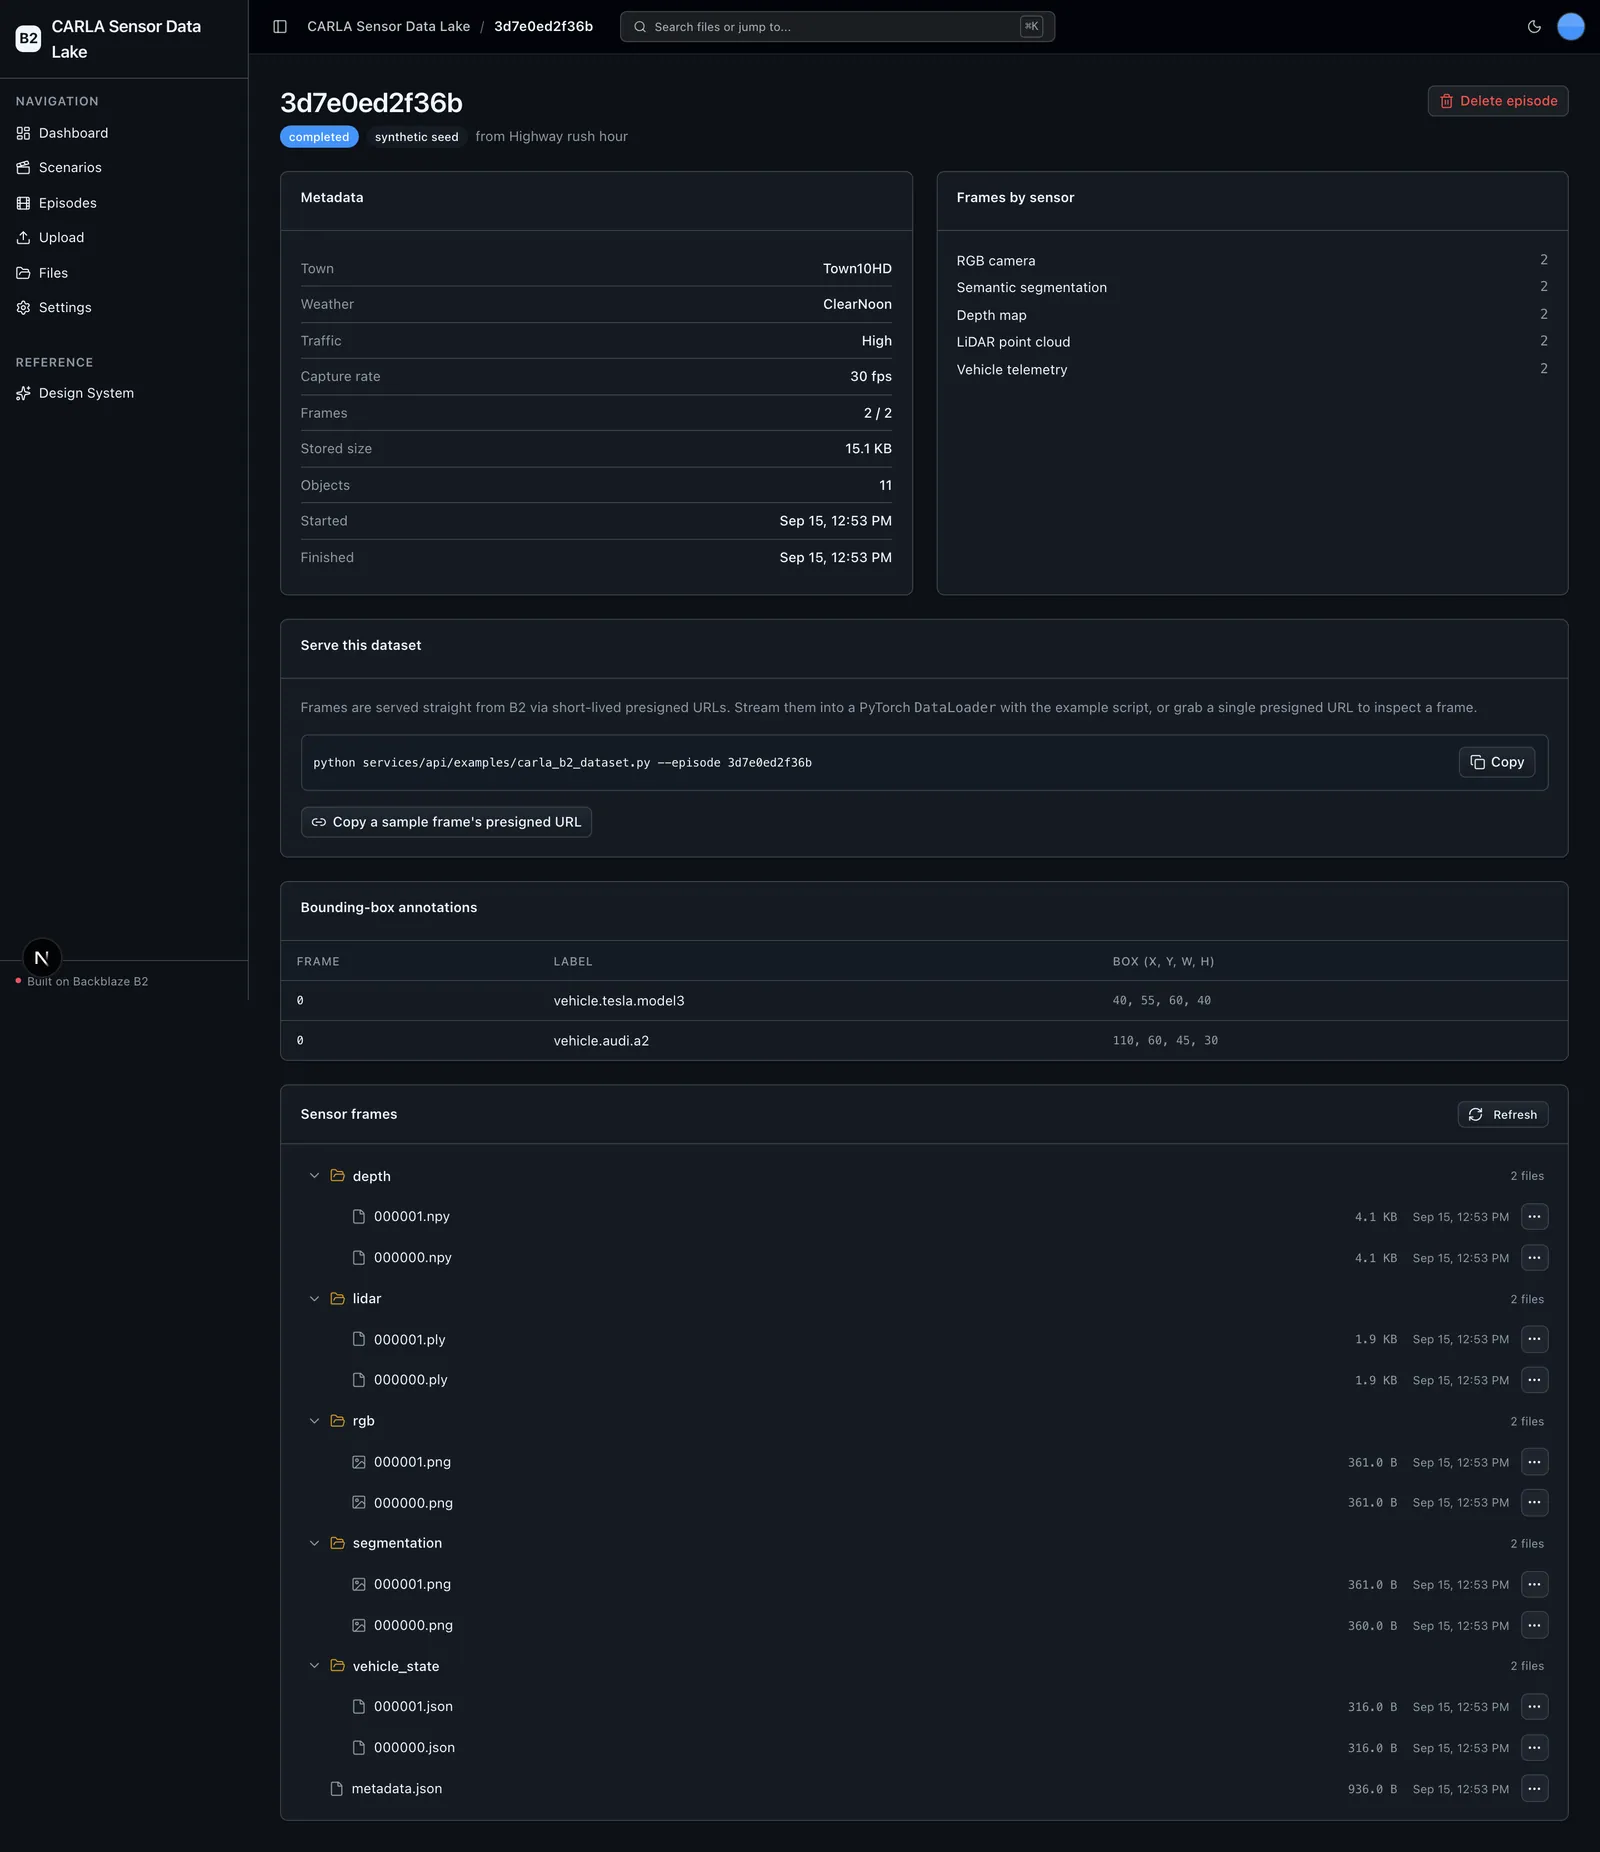
Per-episode metadata and bounding-box annotations with a B2-prefix-scoped sensor-frame browser and presigned-URL preview.
Dataset serving
Presigned-URL frame serving plus a standalone PyTorch DataLoader example that streams straight from B2.
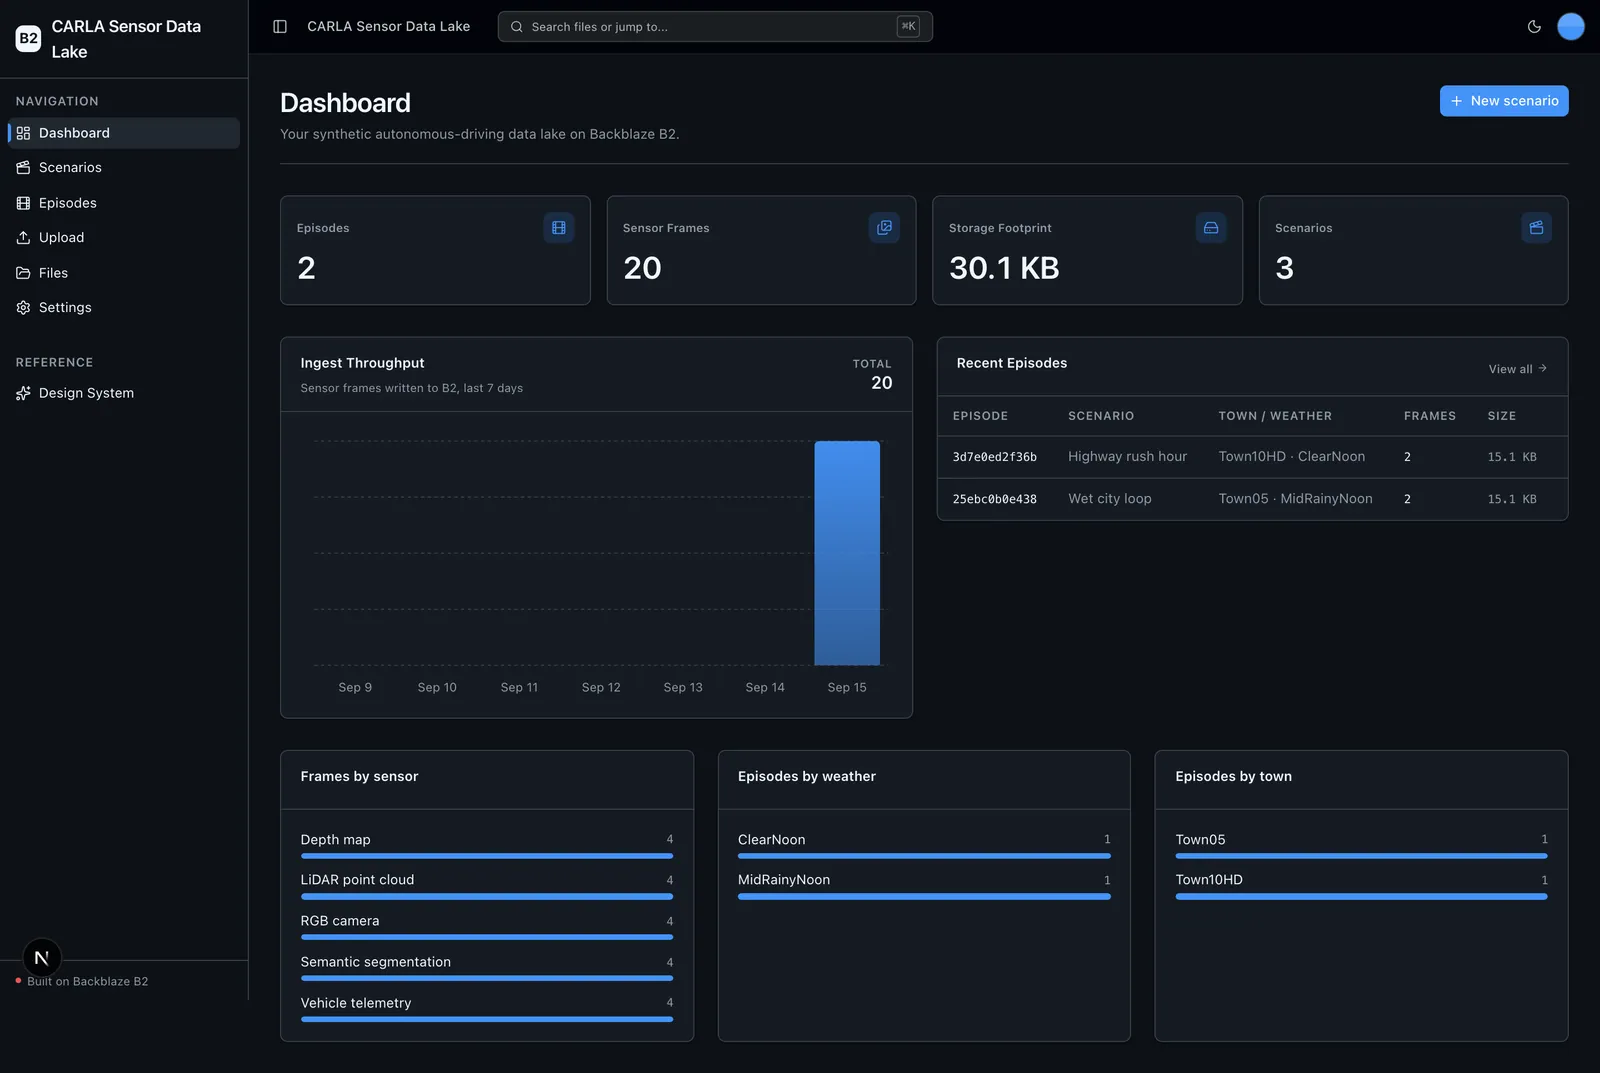
Data-lake dashboard
Episodes, frames, storage footprint, frames-by-sensor, episodes-by-weather/town, and 7-day ingest throughput.
A closer look
More screens from the running project.
Choose it for the right job
CARLA Sensor Data Lake is a head start for a specific shape of project, not a supported, general-purpose product.
Use it when
- You need scalable synthetic multi-sensor driving datasets on cheap object storage.
- You want to manage, browse, and serve datasets already in B2 from any host — no GPU or CARLA server required.
- You want to stream frames straight into a PyTorch DataLoader via short-lived presigned URLs.
Choose another path when
- You need a hosted, multi-tenant SaaS — the API is unauthenticated and bucket-wide by design.
- You want to capture real episodes without a supported Linux/GPU host running a CARLA server (the carla wheel is Linux/Windows, CPython 3.10 and earlier).
- You want a managed training pipeline — the PyTorch DataLoader ships as a standalone example, not an orchestrated trainer.
Project status and support
Report defects via the repository's GitHub Issues; this sample is maintained on a best-effort basis and carries no SLA.